Benchmark results
How many tokens an AI agent spends per task it gets right, measured by Hyperdot's token benchmark and rated by its label. The method is on the label page; how to run the benchmark, in Token benchmark.
Labels
Tested class of Hyperdot 0.1.0: A, from what the self-tests reach.
Tool efficiency
Information sheet · JSON
Information sheet · JSON
Information sheet · JSON
Information sheet · JSON
Reference runs (October 2026)
Hyperdot 0.1.0 at commit e4ccc2e, Claude Code 2.1.309, three runs of every task. These are GitHub Actions runs
39930259189 to 39930286282: 192 sessions (240 calls), $5.95 by Claude Code's figure, run on a subscription. They set the label's scale
(label.md). The table is graded by the current grader, from the saved answers.
| Model | Profile | AEI | Pass | Tokens per solved task | Cost per solved task | Class |
|---|---|---|---|---|---|---|
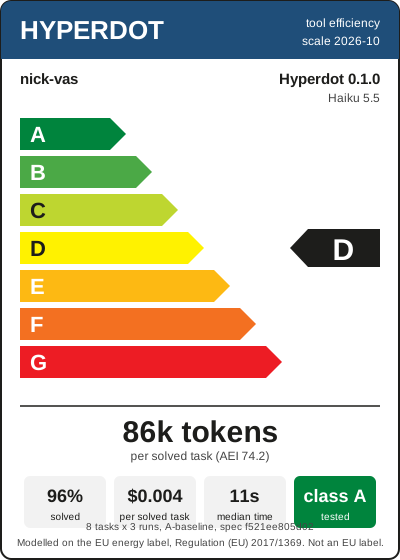
| Haiku 5.5 | A-baseline | 74.2 | 95.8% | 86,041 | $0.0042 | D |
| Haiku 5.5 | B-scoped | 94.5 | 87.5% | 82,355 | $0.0062 | |
| Haiku 5.5 | C-iterative | 120.1 | 100% | 106,040 | $0.0084 | |
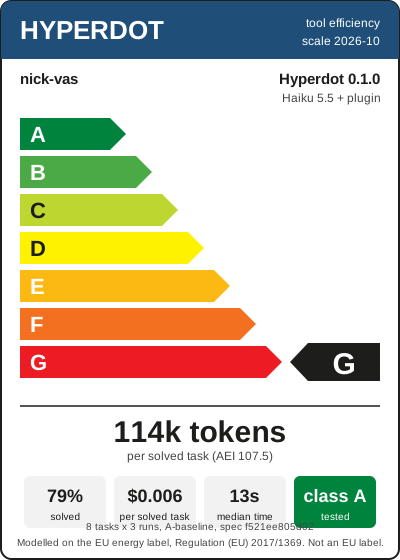
| Haiku 5.5 + plugin | A-baseline | 107.5 | 79.2% | 113,548 | $0.0058 | G |
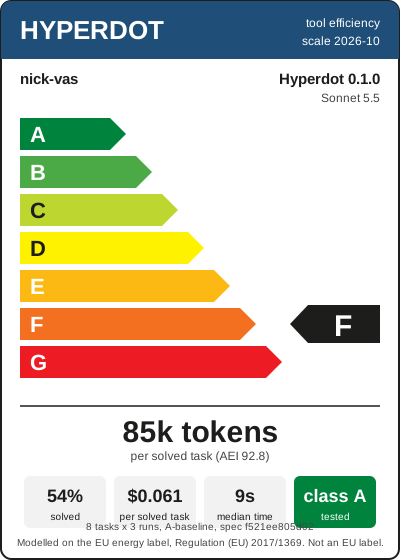
| Sonnet 5.5 | A-baseline | 92.8 | 54.2% | 84,763 | $0.0607 | F |
| Sonnet 5.5 | B-scoped | 124.1 | 45.8% | 100,536 | $0.0847 | |
| Sonnet 5.5 | C-iterative | 167.8 | 66.7% | 133,253 | $0.1713 | |
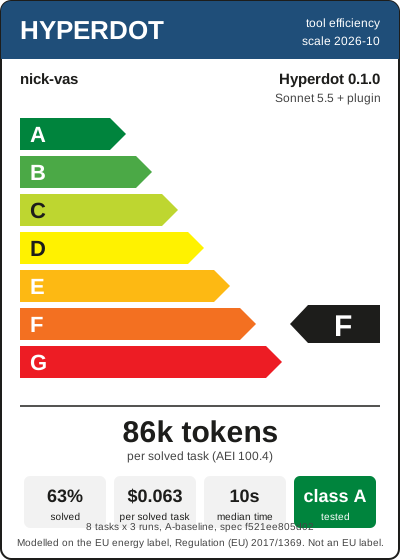
| Sonnet 5.5 + plugin | A-baseline | 100.4 | 62.5% | 85,563 | $0.0633 | F |
The label's information sheets for the four profile-A rows, rebuilt from these runs' saved answers with benchmark/Get-HyperdotLabel.ps1:
Haiku, Haiku + plugin,
Sonnet and Sonnet + plugin. The tested class is A
(index 97.2), from the coverage of the self-test run on commit 0381761.
What they show:
Sonnet fails on length, not on content. All but one of its failed answers, across every profile, are over the word limit their prompt states, by 10 to 30%. Haiku keeps to the limit and passes 96% under profile A, at about a fifteenth of the cost per solved task.
The plugin costs here and shows no reliable gain. Its 51 skills are about making games, and these tasks are about Hyperdot's own code. Loading it adds tokens to every session: the index rises from 74.2 to 107.5 for Haiku and from 92.8 to 100.4 for Sonnet. Haiku's pass rate falls from 96% to 79%, Sonnet's rises from 54% to 62% (two tasks of 24, within noise).
evals/is where the plugin is meant to help: game tasks.Scoping and planning do not pay on these tasks. B (listed files, a turn limit) and C (plan, then answer) both cost more per solved task than A for both models. C's second step resends the whole session, and B's sessions that ran out of turns still spent their tokens.
Reading every failure found three grader faults, fixed before the scale was set:
- CI-PS-001 required the word "scope", which good answers did not use;
- CODE-PS-001 required
param(, though the repository writes 259 functions with inline parameters and 21 withparamblocks; - markup was counted as words.
The adversarial review had already found the faults that let wrong answers pass: substring matches, terms echoed from the prompt, a readable spec.
Earlier runs (Sonnet on 2026-10-23 07:45 and 08:11, Haiku at 08:23, Sonnet with the plugin at 08:50) used a grader and sessions that could read the spec. They are superseded by the runs above.
From Token benchmark.
Field test: one owner's game
Not part of the class. The owner ran the field test (-GameSource, token-benchmark.md)
on a game of their own, which nobody else can repeat, so these numbers are informative only: they say how the
configurations did on one real game, not how Hyperdot rates.
| Template | Configuration | Runs | Passed | Median tokens | Median cost | Median time (s) |
|---|---|---|---|---|---|---|
| (not run yet) |
benchmark/Get-HyperdotLabel.ps1 computes the label from benchmark runs (-Programme tool or game).
benchmark/label-scale.json holds the scale: the classes and minimum requirements, and for each programme its spec, its
standard tokens per task and its tolerances. tests/Test-HyperdotLabel.ps1
checks both.
From The Hyperdot label.